Integrate and compare LLM APIs
Start with NixAPI Blog
NixAPI is an LLM relay for developers supporting OpenAI, Claude, Gemini, DeepSeek, Qwen, and Grok. This blog helps developers compare models, integrate APIs, optimize costs, and ship production features faster.
Low-latency Relay
Global acceleration nodes, avg. response < 1s, 99.9% uptime SLA.
OpenAI Compatible
Fully compatible OpenAI API — swap your base_url and you're done.
All-in-one Model Access
Access OpenAI, Claude, Gemini, DeepSeek, Qwen, and Grok through one API key and one integration path.
Top up ¥1 = $1
Pay as you go with no monthly fee and predictable pricing for teams, solo devs, and products.
OpenAI, Claude, Gemini, and DeepSeek API Guides
OpenAI, Claude, Gemini, and DeepSeek integration guides
Find tutorials for OpenAI API, Claude API, Gemini API, and DeepSeek API, plus model comparisons, streaming responses, and cost optimization for production use.
Latest Articles
View all →
Gemini 3.8 Flash Onboarding: New Interactions API Mode, 1,048,576 Context Window, and the 9-Item Migration Checklist
Google released Gemini 3.8 Flash on September 22, 2026. The model ID is gemini-3.8-flash, with native 1,048,576 token context, 65,536 token output, and tunable thinking level (low/medium/high). Google simultaneously elevated the new Interactions API as the recommended primary path (server-side state via previous_interaction_id + steps timeline), while keeping generateContent as legacy. This article covers model specs, intro pricing ($0.75/$3.75 through Dec 31, 2026), the two API shapes, the 9-item migration list (including required call_id/name fields and thought-signature preservation), code examples, and the NixAPI integration strategy.
StepFun Step 5 Preview Deep Dive: How a 600B Sparse MoE at $1 / $2.70 per MTok Is Rewriting the September API Price War
On September 20, 2026, StepFun released Step 5 Preview — a 600B-parameter sparse MoE with only 27B active per token, 1M-token context, native vision input, and an Artificial Analysis Intelligence Index of 44 (tied with Kimi K3 Max). API pricing: $1.00 input / $2.70 output per MTok with a 95% cache discount; open-weights release scheduled for October 15. This article dissects architecture, pricing, benchmarks, market positioning, and what global developers should do.
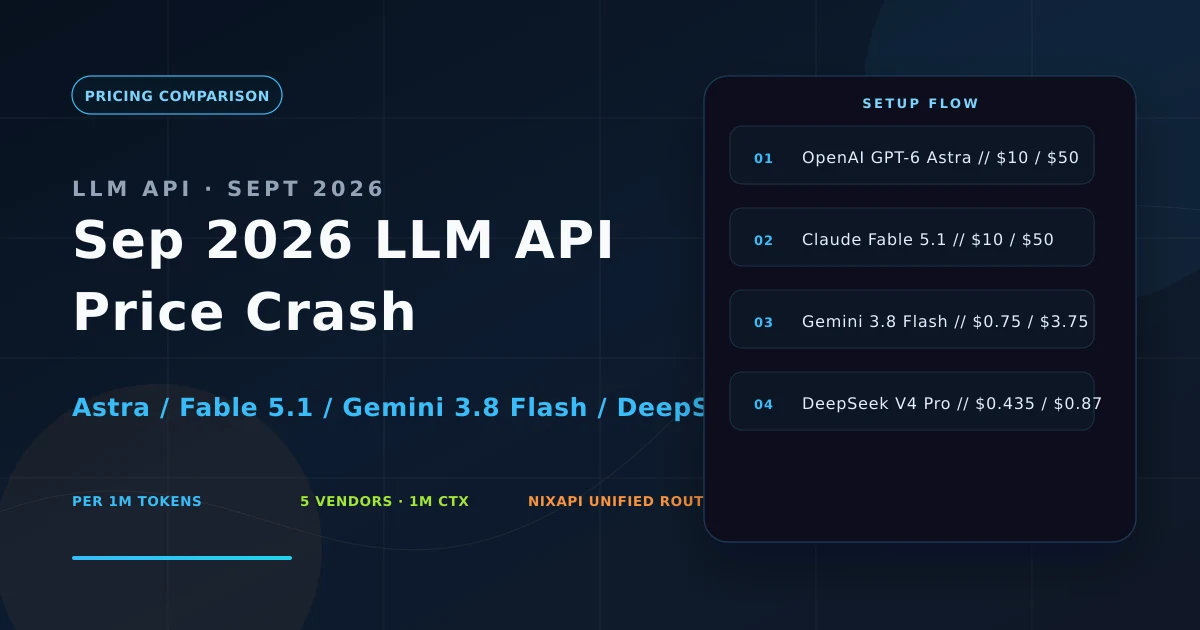
September 2026 LLM API Price Crash: A Full 5-Vendor Comparison (GPT-6 Astra vs Fable 5.1 vs Gemini 3.8 Flash vs DeepSeek V4 Pro)
In the first week of September 2026, OpenAI GPT-6 Astra, Anthropic Claude Fable 5.1, and Google Gemini 3.8 Flash launched within days of each other — plus Sonnet 5 pricing went permanent and DeepSeek V4 Pro slashed rates. This article gives a full per-million-token price comparison table, cache pricing, context windows, real benchmark numbers, and a unified-routing strategy via NixAPI.
OpenAI Astra Deep Dive: The First Model Rated Critical for Cybersecurity — What ExploitBench 100% Really Means
OpenAI released Astra on September 1, 2026 — the first model OpenAI has classified as Critical for cybersecurity. It scored 100% on ExploitBench and can autonomously discover 0-day vulnerabilities. OpenAI notified the White House, delayed the rollout, and gated access. This article dissects Astra's capabilities, ExploitBench's significance, the new cooperative-governance pattern, current API status, and how to prepare via aggregate API platforms like NixAPI.
DeepSeek V4 Pro Price Hike: Peak/Off-Peak Pricing Arrives, How Should Developers Respond?
DeepSeek V4 Pro API output price jumps from $0.87 to $3.96 per million tokens—a 4×+ increase. Deep dive into the new peak/off-peak pricing, cost impact, and developer mitigation strategies.
Google Gemini 3.7 Flash Released: Major Coding & Agent Gains, Pricing Strategy Explained
Google launches Gemini 3.7 Flash just 3 weeks after 3.6 Flash, with big benchmark gains on coding and agentic workflows and an aggressive introductory API price of $0.75/M input tokens.